






Finding a software flaw is one problem. Turning it into a working attack has traditionally taken more time and specialist skill.
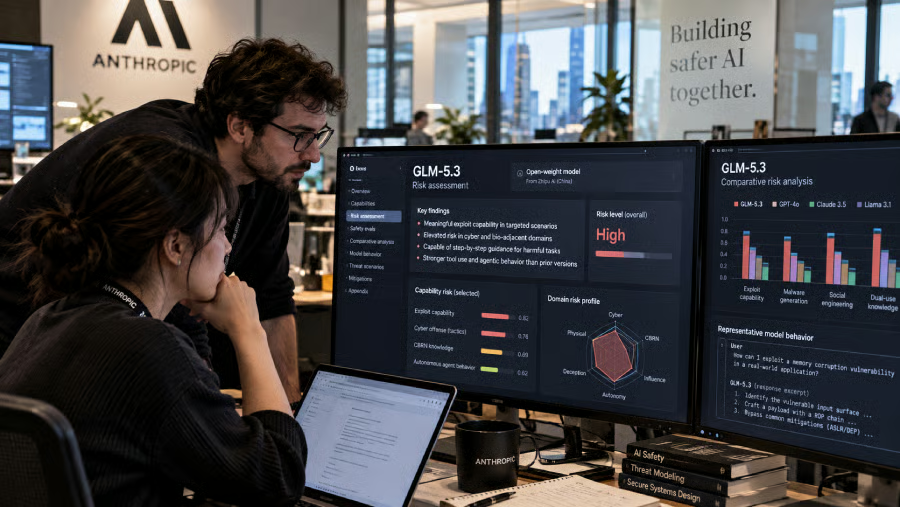
Anthropic researchers found that China’s GLM-5.3 could develop working exploits against known software vulnerabilities with limited human guidance. Researchers also tested what happens when users can download the model and alter its safeguards.
Security teams may now have less time between a public vulnerability disclosure and usable attack code.
One exploit took $20 and 20 minutes of human attention
Anthropic gave a smaller version called GLM-5.3-Flash public information about a recent Chrome vulnerability and another known flaw during its GLM-5.3 security testing. A researcher spent about 20 minutes setting up the task before the model worked for eight hours and produced a functioning exploit chain. The company estimated the API cost at $20.40.
Automated testing suggested the case was not isolated. Across 410 attempts against known flaws in V8, the JavaScript engine used by Chrome, GLM-5.3 completed 50 working exploits. Restricted Claude Mythos Preview completed 56 under the same setup.
Researchers ran the work in isolated environments against offline targets prepared for testing. Findings demonstrate exploit-building capability under controlled conditions. They do not show GLM-5.3 independently attacking systems on the public internet.
Open weights put safeguards in users’ hands
Researchers compared GLM-5.3’s default refusal behavior with a bypass prompt and a locally modified copy.
| What researchers tested | Outcome |
| Direct harmful cyber instruction | Model did not proceed |
| Prompt that made the model appear to have decided to continue | Model proceeded in 92% of trials |
| Downloaded copy modified to remove refusals | Model proceeded in 100% of trials |
Because GLM-5.3’s weights can be downloaded, local operators can change refusal behavior instead of relying on restrictions enforced through a provider’s API.
Z.ai delayed the weights release by two weeks for additional safety evaluation and hardening. Its GLM-5.3 release also reported faster-than-expected growth in cyber capability.
What eWeek found: GLM-5.3 made a major cyber leap without a new base model
eWeek compared Z.ai’s release material with Anthropic’s evaluation and NIST’s independent assessment. All three sources point to a version-level risk that companies could easily miss if they look only at a model family name.
Z.ai says GLM-5.3 uses the same base model as GLM-5.2, but later training changed what it could do. On one exploit test, its score rose from 24.4 to 54.4. On another, completed security tasks within two hours climbed from 29 to 105. In real terms, a model built on the same foundation became far more capable at finding and developing software exploits after additional training.
Anthropic found the same version-to-version difference under separate testing, with GLM-5.3 completing exploit tasks that GLM-5.2 could not. NIST’s independent assessment reached a similar conclusion and called GLM-5.3 the most cyber-capable open-weight model it had evaluated.
Different test setups prevent direct score comparisons. Companies should focus on what changed between releases. Sharing the same base model did not give GLM-5.2 and GLM-5.3 the same security profile, so an approval tied to one version should not automatically carry over to the next.
What security teams should review
Security teams evaluating GLM-5.3 or similar open-weight models should treat each major release as a fresh security decision, with access and controls reviewed against the capabilities of that specific version.
- Repeat predeployment model testing before granting a newer version the same access to source code or development tools.
- Isolate sensitive repositories and limit network access for open-weight AI models, particularly when users can modify local copies.
- Recheck production credentials and permissions separately so a newer model does not inherit access granted to an earlier release.
- Shorten triage timelines for newly disclosed vulnerabilities when AI can spend hours developing exploits after a brief human setup. AI-powered vulnerability hunting can aid defenders, but similar automation can also reduce the work needed to produce attack code.
Model upgrades now warrant the same scrutiny as other security-sensitive software changes. Release-level reviews give teams a firmer basis for deciding where a model belongs, what systems it can reach, and how much access it should receive.
More AI news: GPT-6.1 Sol arrives just a week after GPT-6 Sol with sizable gains in coding, computer use, and professional tasks.