




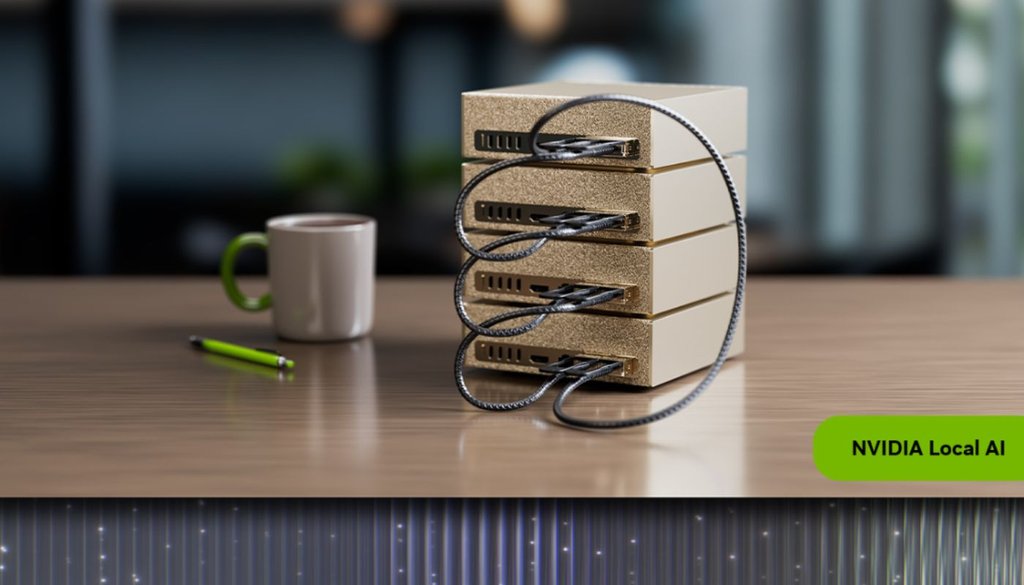
Researchers have traditionally relied on shared GPU clusters and supercomputers to run computationally demanding AI and scientific workloads. Nvidia wants to bring some of that computing capability closer to individual research teams with a new four-system DGX Spark cluster.
At the SC26 event in Chicago on Nov. 16, Nvidia announced the DGX Spark HPC Developer Kit to bring local supercomputing to researchers' desks. The new product includes four DGX Spark systems, 512GB of combined memory, 16TB of NVMe storage, and ConnectX-7 networking in the HPC cluster configuration. However, the Nvidia HPC SDK installation playbook will come later.
Nvidia says that this new system can run an AI model with up to 700 billion parameters. For comparison, one DGX Spark system with 128 GB RAM can only accommodate a model of up to 200 billion parameters.
By clustering four DGX Spark systems, Nvidia is able to deliver a local AI platform that would ordinarily require researchers to use a shared GPU cluster.
The new DGX platform is available for purchase via the Nvidia Marketplace and through OEM partners like Acer, Dell and Lenovo.
What researchers can do with the DGX Spark HPC Developer Kit
Nvidia is extending DGX Spark beyond standalone desktop AI computing into multi-node HPC development. With this new HPC configuration, researchers can:
- Develop and test scientific applications: Support for applications such as LAMMPS, NAMD, GROMACS, OpenFOAM and WRF.
- Experiment with larger AI models: Distribute models across the four systems
- Use familiar HPC development tools: Use C, C++, and Fortran compilers, and GPU-accelerated libraries.
After experimenting on their local DGX systems, researchers can then move their workloads to more powerful supercomputers if needed.
What eWEEK found: Desktop HPC still has to prove its value at scale
Nvidia is making HPC development more accessible, but a four-node desktop cluster is not a replacement for large-scale supercomputing infrastructure. Its value depends on how effectively researchers can use it to develop, test and optimize workloads before moving them into production environments.
Researchers still need to answer two key questions before deciding whether adopting the DGX systems provides more value than their current workflow:
- Performance: Does the combined memory and computing capacity adequately support the workloads researchers want to run locally? It may be better if the researcher directly used a supercomputer.
- Scalability: Can applications developed on this cluster transition to larger GPU clusters and supercomputers? If the larger HPC platform uses a different technology like Tensor Processing Units (TPUs), this may make it a challenge for the researcher to scale their application later on.
A desktop cluster could shorten the time it takes to fix a simulation even if the simulation itself runs more slowly there.
For teams that repeatedly change inputs or debug how nodes exchange data, the useful comparison is the time from editing the code to getting a result they can act on. That includes the time a job spends waiting for a shared cluster.
Before buying, a lab could run one representative workload through both workflows. Track how many test cycles the team completes in a day, then run the revised workload on the intended production system to check its results and scaling. That would show whether the desktop kit saves researchers time on work they do regularly.
What this means for enterprises
Research institutions and enterprises can experiment with the multi-node AI and HPC workloads without immediately procuring large-scale infrastructure.
Nvidia says that its DGX platform supports open models like Nemotron 3.5 and Deepseek 4.1. Therefore, researchers have an opportunity to test workload suitability without the bill that comes with proprietary models. However, running open models locally still carries hardware, energy and infrastructure costs.
Enterprises can also use the kit to evaluate the practical value of desktop HPC infrastructure before expanding their deployments. For example, research institutions can assess whether the computing capacity, memory and networking capabilities meet their researchers' requirements.
Beyond infrastructure savings, a localized cluster lowers the barrier to training staff on distributed computing. Junior engineers and domain scientists can practice message-passing interfaces, multi-node debugging, and parallel optimization on dedicated hardware without risking disruption to shared production environments.
While organizations still need to account for upfront hardware, power, and cooling expenses, a desktop cluster shifts experimentation from unpredictable cloud consumption to a controlled capital expense. That gives IT leaders concrete utilization metrics and cost baselines before greenlighting larger, rack-scale deployments.
Other news: Apple’s macOS 27.3 beta lets users limit some apps to specific protected folders or choose which other apps they can control.